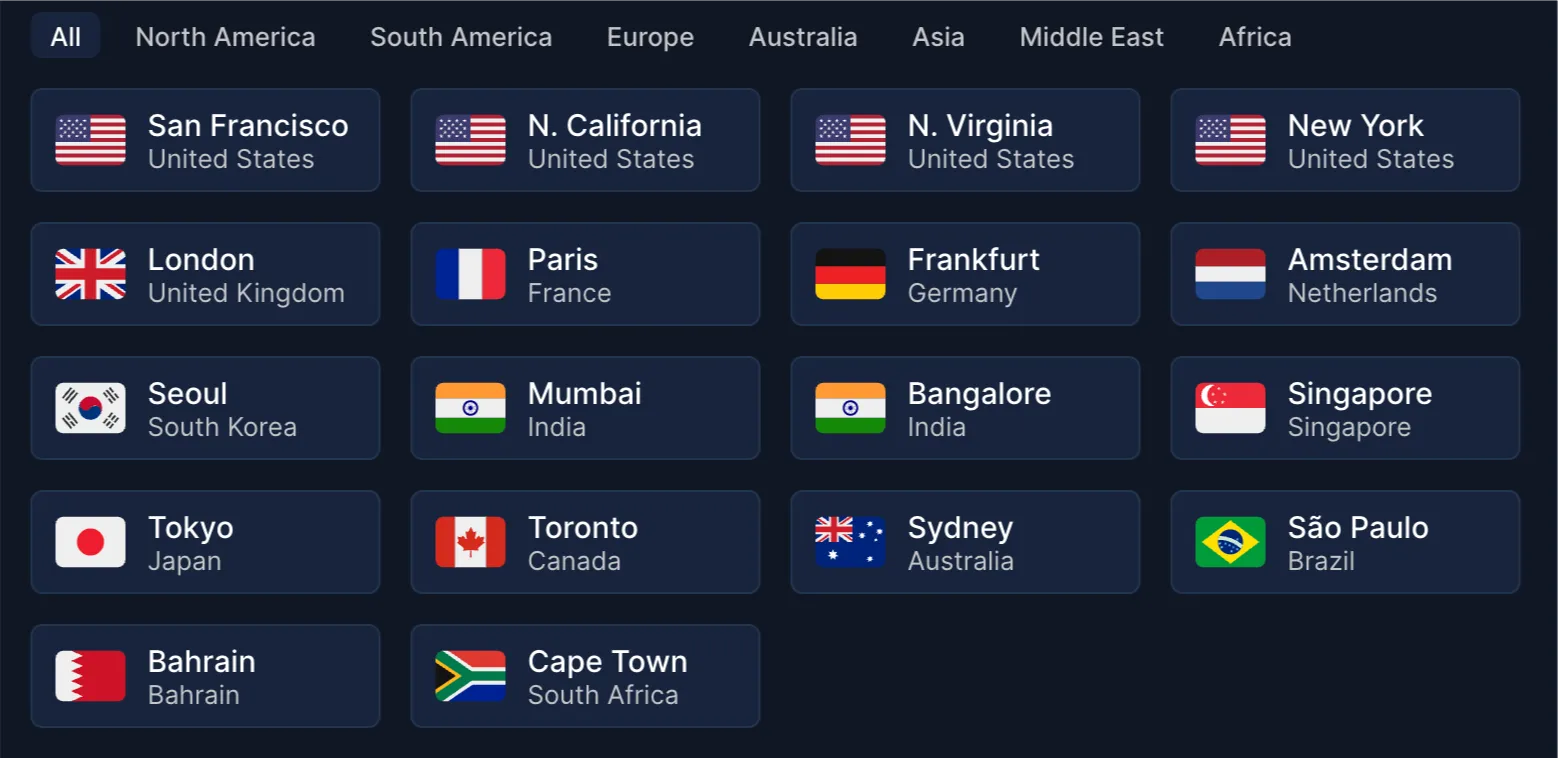
Uptime monitoring is black-box monitoring: Hyperping sends requests to your websites, APIs, ports, and DNS records from up to 18 regions on the public internet, and checks what comes back. It sees what a customer would see, including failures in DNS, the CDN, certificates, and routing that no metric inside your servers records.
Black-box vs white-box monitoring
White-box monitoring reads the system's internals: CPU, memory, queue depth, error rates, logs, and traces. It explains why something is slow or failing. Black-box monitoring only tells you that it is, from the user's side.
You need both, for different jobs. Page on black-box signals, because they mean users are affected right now. Use white-box signals to diagnose, and for the slow problems that haven't reached users yet, like a disk filling up over days. A team with only white-box monitoring sees green dashboards while users can't resolve the domain. A team with only black-box monitoring knows the site is down and has no idea why.
Failures black-box monitoring catches
- The whole site or API being unreachable.
- DNS records deleted, changed, or failing to resolve.
- Expired or misconfigured SSL certificates.
- CDN and load balancer failures in front of healthy servers.
- Regional problems, where users in one part of the world can't connect.
- Pages that load but are broken, caught with keyword checks or scripted browser checks.
Types of black-box checks
- HTTP checks on pages and API endpoints, with status code and content assertions.
- Ping (ICMP) and TCP port checks for hosts and services that don't speak HTTP.
- DNS checks on individual records.
- Certificate and domain expiry checks.
- Synthetic browser checks that log in, search, or check out like a real user.
Limits of black-box monitoring
It sees symptoms, not causes, and only for what you check. An endpoint you don't monitor can be down for days. It also can't reach anything that isn't public: internal services need a heartbeat or an agent instead. And a check is a sample, so a failure that affects 1% of requests may pass most checks. Pair it with error rates from inside the application for that case.
FAQ
Is synthetic monitoring black-box monitoring?
Yes. Synthetic checks are scripted black-box tests: they use the product from the outside without access to its internals.
Is black-box monitoring the same as external monitoring?
Nearly. External monitoring describes where checks run from, outside your network. Black-box describes what they know, nothing about the internals. In practice the terms are used for the same tools.
Where should black-box checks run from?
From outside your own network and cloud provider, in the regions your users are in. A check from inside the same data center misses exactly the failures black-box monitoring is for.